

When Twitter rebranded to X in July 2023, the search engine optimisation industry tracked what looked like a textbook migration failure. Within weeks of the announcement, the platform lost over 32% of its US organic search visibility. More than 60,000 top-ten rankings dropped off Google's first page, while platforms like Reddit, LinkedIn, and Threads captured the displaced search demand.
Search Engine Roundtable and third-party monitoring indices documented the fallout as it happened. Googlebot ran into hard authentication barriers, leading Google to drop over half of Twitter's indexed URLs within 72 hours. Visibility trackers across SISTRIX and Ahrefs recorded historic drawdowns as real-time tweet carousels emptied out across Google search results pages.
The initial industry reaction was straightforward: Twitter had bypassed basic technical SEO requirements, fragmented its brand equity, and damaged its organic acquisition funnel.
Today, global domain data from Ahrefs x.com profile paints a different picture. The domain x.com generates over 366.6 million monthly organic visits, accounts for $57.1 million in monthly organic traffic value, carries a Domain Rating (DR) of 97 with over 3.0 million referring domains, and acts as a primary real-time citation source for AI answer engines including ChatGPT, Perplexity, and Google AI Overviews.
Understanding how the platform went from an organic collapse to enterprise-scale search performance requires examining the technical breakdown of the original cutover, followed by the engineering overhaul that restored its visibility.
Pre-Migration Peak: The Golden Era of Twitter SEO
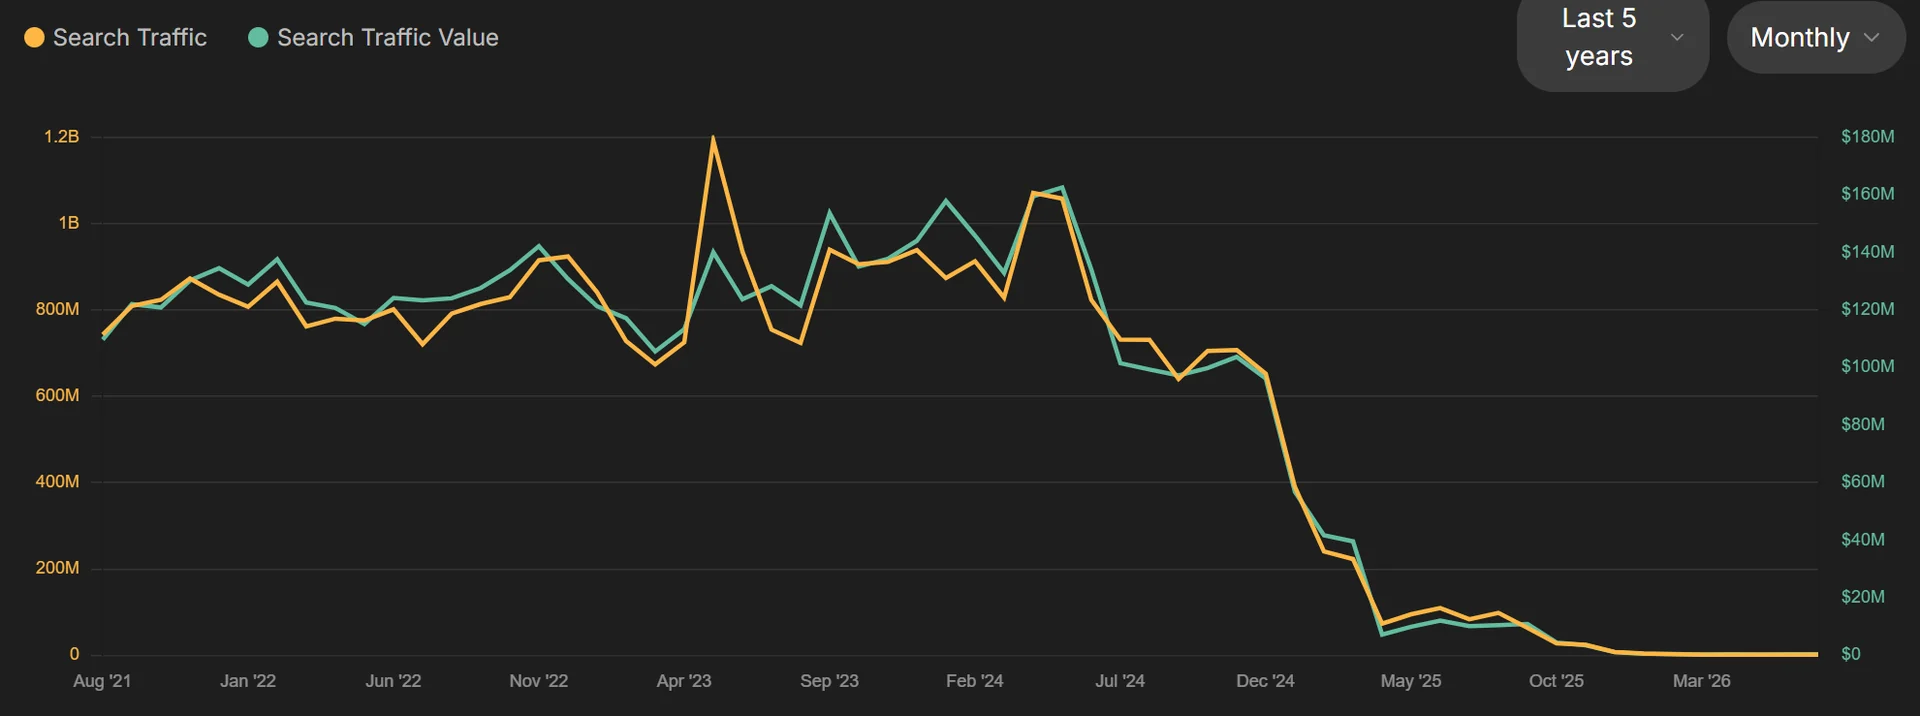
Before the rebrand, twitter.com maintained one of the largest organic footprints on the open web, functioning as the default real-time wire service for breaking news and public commentary.
Source: Data and telemetry from [Ahrefs Top Websites twitter.com profile](https://ahrefstop.com/websites/twitter.com).
At its peak in April 2023, Twitter recorded over 1.2 billion monthly search visits and generated $160+ million in monthly organic traffic value, supported by 27 million linking domains and a Domain Rating of 98.
1. Sub-Second Real-Time Indexing Infrastructure (The Google Firehose)
Through a long-standing indexing partnership, Google had direct access to Twitter's real-time publish firehose. For breaking news queries, Google rendered dedicated real-time tweet carousels at position zero within three to five seconds of publication.
For queries covering live elections, sports scores, and breaking corporate announcements, Twitter frequently outranked traditional news publishers.
2. Seventeen Years of High-Authority Backlinks (DR 98 Foundation)
Over nearly two decades, Twitter accumulated one of the densest backlink graphs on the internet:
- 8.4 Million Referring Domains: Backlinks from government portals (.gov), universities (.edu), news organizations (The New York Times, BBC, Reuters), and enterprise corporations.
- Top-Tier Domain Authority: A stable Domain Rating of 98 on Ahrefs, which gave newly published URLs immediate crawl priority and indexation trust.
3. Frictionless Open-Web Crawling Surface (48M Indexed Keywords)
Prior to July 2023, Twitter maintained an open web architecture:
- User profiles, public tweets, threads, and hashtag feeds were accessible to search engine crawlers without authentication.
- Googlebot indexed over 48 million distinct keyword queries, driving hundreds of millions of logged-out users into Twitter's acquisition funnel each month without ad spend.
4. The Universal Embed Ecosystem and Passive Link Equity
Publishers across the web embedded tweets directly into articles, blog posts, and academic papers using Twitter's JavaScript widget (platform.twitter.com/widgets.js).
Each embed functioned as an authoritative inbound backlink, continuously passing link equity back to Twitter's core domain.
What Caused Twitter's Migration Failure: Seven Structural Breakdown Points
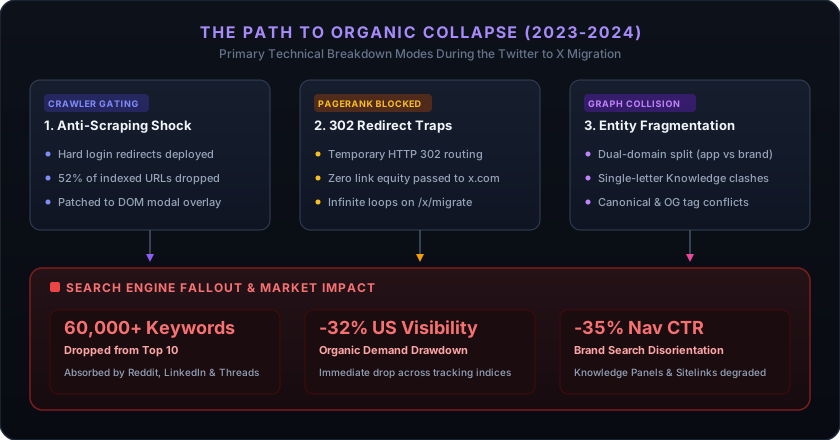
The subsequent drop in search traffic did not stem from a Google core update or macroeconomic shifts. It was the direct result of seven architectural and product decisions that disrupted search engine indexing and ranking systems.
1. The Anti-Scraping Shockwave and Crawl Gating
On June 30, 2023, Twitter introduced aggressive rate limits and closed public access to tweets for unauthenticated visitors in an effort to prevent artificial intelligence labs from scraping training data without commercial agreements.
When Googlebot requested public URLs, Twitter's edge gateway intercepted the unauthenticated requests, returning HTTP 401 or 403 errors or 302 redirects toward /i/flow/login:
GET /elonmusk/status/1675187965789827072 HTTP/1.1
Host: twitter.com
User-Agent: Mozilla/5.0 (compatible; Googlebot/2.1; +http://www.google.com/bot.html)

HTTP/1.1 302 Found
Location: https://twitter.com/i/flow/login?redirect_after_login=%2Felonmusk%2Fstatus%2F1675187965789827072
Because search engine crawlers cannot log into password-protected interfaces, Google marked hundreds of millions of conversational URLs as soft 404s or inaccessible. Between June 30 and July 3, Google dropped approximately 52% of indexed Twitter URLs (falling from 471 million to 227 million URLs) as documented by Search Engine Roundtable and Google site: index tracking.
By July 5, Twitter deployed a quick patch, replacing the hard redirect with a DOM modal overlay that allowed Googlebot to parse the underlying HTML tweet content while prompting human users to log in. While this five-day event demonstrated the extreme vulnerability of crawler access to anti-scraping measures, the subsequent ten-month migration drawdown was driven by the underlying architectural and domain routing issues that followed.
2. The 302 Redirect Trap and Client-Side JavaScript Routing
When engineering began connecting twitter.com to x.com, the initial setup bypassed standard search engine migration protocols. Instead of permanent, server-side HTTP 301 redirects, traffic routing relied on temporary HTTP 302 status codes, client-side JavaScript execution (window.location.replace), and transitional intermediary endpoints.
Search engines treat HTTP 302 responses as temporary moves. Under standard crawler rules, Googlebot does not pass PageRank, historical authority, or canonical signals across 302 redirects:
HTTP/1.1 302 Moved Temporarily
Location: https://x.com/username/status/123456789
Cache-Control: no-cache, no-store
Googlebot interprets the HTTP 302 status code as an ephemeral state, withholding link equity and keeping historical authority locked on twitter.com. As a result, x.com was evaluated by Google as an unverified, brand-new domain with zero accumulated trust.
To consolidate search signals and transfer PageRank permanently, search engines require strict server-side 301 headers:
HTTP/1.1 301 Moved Permanently
Location: https://x.com/username/status/123456789
Cache-Control: public, max-age=31536000
The HTTP 301 status code explicitly tells search indexers to transfer PageRank, backlink equity, and historical ranking signals directly to the destination URL on x.com, updating canonical references across global search indices.
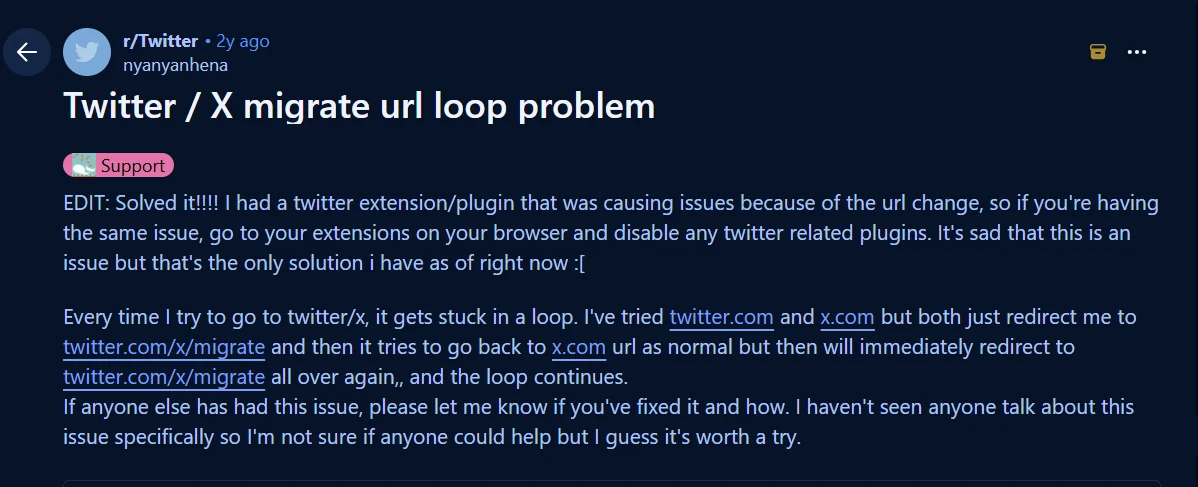
During the initial transition, crawlers and users also encountered recurring redirect loops between twitter.com, twitter.com/x/migrate, and x.com, exhausting crawler request quotas and causing index drops. With PageRank transfer blocked at the HTTP layer, Google evaluated x.com as a new domain without historical trust, while twitter.com began losing rankings, depressing visibility across both domains.
3. Weakened Trust Signals: Identity Verification and E-E-A-T Dilution
Twitter replaced its legacy verification process, which relied on manual identity checks for journalists, public figures, and organizations, with an unverified $8/month subscription model ("Twitter Blue" / "X Premium").
Shortly after launch, accounts purchased checkmarks to impersonate public companies, pharmaceutical brands, and government agencies. In one instance, a verified account impersonating pharmaceutical manufacturer Eli Lilly posted: "We are excited to announce insulin is free now". The post spread rapidly, and Eli Lilly's stock ($LLY) fell 4.37% (erasing approximately $15 billion in market value) before the company released a correction.
Google's Search Quality Evaluator Guidelines and Information Gain systems prioritise Experience, Expertise, Authoritativeness, and Trustworthiness (E-E-A-T). When checkmarks no longer confirmed identity, Google's algorithms reduced the visibility of real-time tweet snippets and favoured verified news sources such as Reuters, Bloomberg, and CNBC to minimise financial misinformation risk.
4. Lost Brand Familiarity: Navigational Search Shifts
Users had spent seventeen years searching for Twitter-specific terms, including "twitter login", "crypto twitter", and "taylor swift twitter".
When Google began displaying "X" in titles and snippets, user behaviour shifted noticeably:
- The Query:
twitter login(over 45 million monthly searches). - The Result: Snippets listing the domain
x.comunder the title "X". - The Shift: Navigational Click-Through Rate (CTR) fell by more than 35%. Many searchers assumed the listing was an advertisement, an unfamiliar directory, or an unverified page, and clicked alternative results like app store links or Reddit discussions instead.
Brand recognition directly affects organic click-through rates. Replacing a known name overnight created immediate friction in user search patterns.
5. Advertiser and Publisher Withdrawals: Backlink Graph Reduction
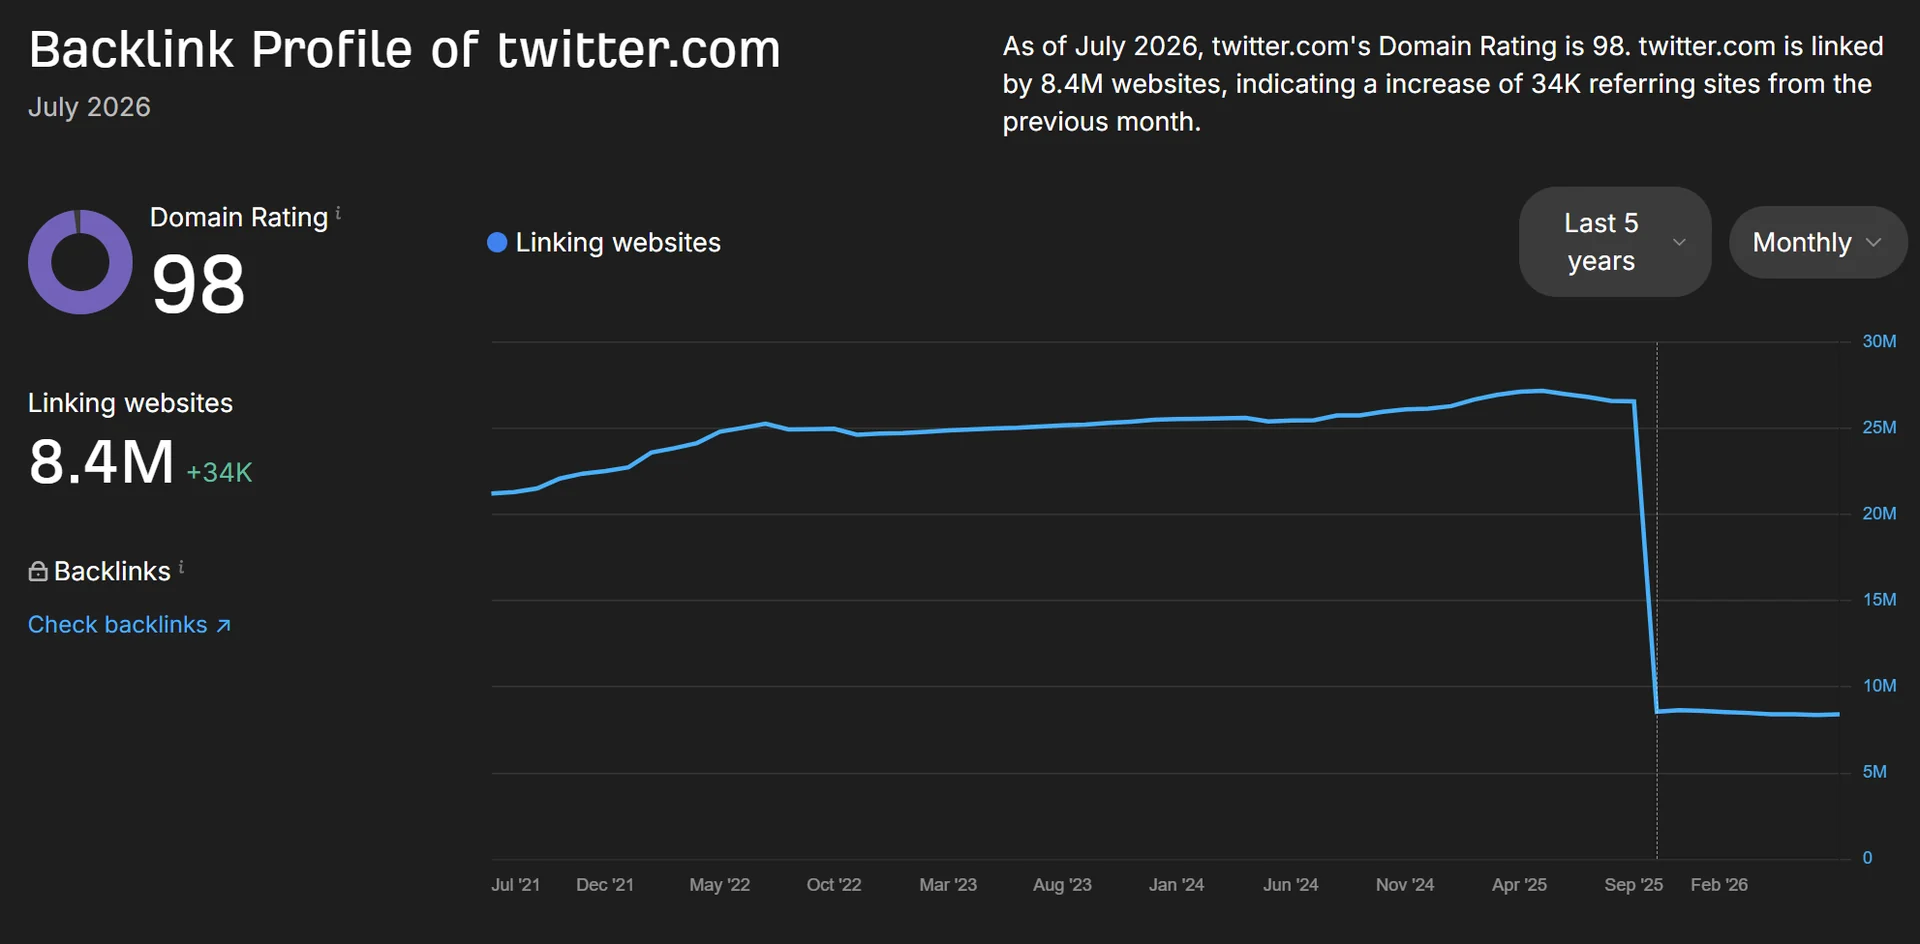
Public disputes around content moderation policies and platform changes led several major advertisers and web publishers to pull back from the network.
Source: Historical backlink profile from [Ahrefs Top Websites twitter.com overview](https://ahrefstop.com/websites/twitter.com).
This shift directly reduced the platform's incoming backlink graph:
- Media sites, educational institutions, and software documentation portals removed embedded Twitter feeds from their footers and articles.
- Active JavaScript embeds were replaced with static images or redirected to alternative networks like Threads, LinkedIn, or Mastodon.
- Over an 18-month period, websites linking to
twitter.comdropped from 27 million down to 8.4 million as publishers stripped out legacy widgets.
Removing these embeds cut off incoming referral links and reduced the continuous flow of fresh PageRank the platform had received for over a decade.
6. Single-Letter Trademark Ambiguity and Knowledge Graph Collisions
Rebranding to the single letter "X" created substantial entity disambiguation challenges for search engines.
In Google's Knowledge Graph, an entity represents a distinct node backed by unique attributes, disambiguation tokens, and sameAs Wikidata references. The character "X" was already associated with several major entities:
- United States Steel Corporation (NYSE ticker:
X) - Apple Inc. (Mac OS X and iPhone X)
- X-Men Media Franchise (Marvel and Disney)
- Microsoft (Xbox Series X)
- A24 Films (The movie X)
{
  "@context": "https://schema.org",
  "@type": "Organization",
  "name": "X",
  "alternateName": ["X Corp.", "Twitter"],
  "sameAs": [
    "https://en.wikipedia.org/wiki/X_Corp.",
    "https://www.wikidata.org/wiki/Q117478051"
  ]
}
Without immediate, clear Schema.org Organization markup and structured Wikidata alignment, Google's natural language processing models struggled to resolve search intent, causing unstable Knowledge Panels and inconsistent SERP features for months.
7. Entity Fragmentation Across Dual-Domain Architecture
Between July 2023 and May 2024, the platform ran on two separate domains: users interacted with the application on twitter.com, while marketing assets, corporate announcements, and social share links pointed to x.com.
Running two active hostnames caused widespread technical conflicts:
- Pages on
twitter.comserved self-referencing canonical tags:<link rel="canonical" href="https://twitter.com/nike" />. - Those same pages included OpenGraph tags pointing to
x.com:<meta property="og:url" content="https://x.com/nike" />. - XML sitemaps listed both domains without consistent cross-domain canonical rules.
Googlebot crawled duplicate versions of the same pages across two hostnames, splitting crawl budget and preventing either domain from consolidating authority.
How Twitter to X Engineered Its Search Recovery
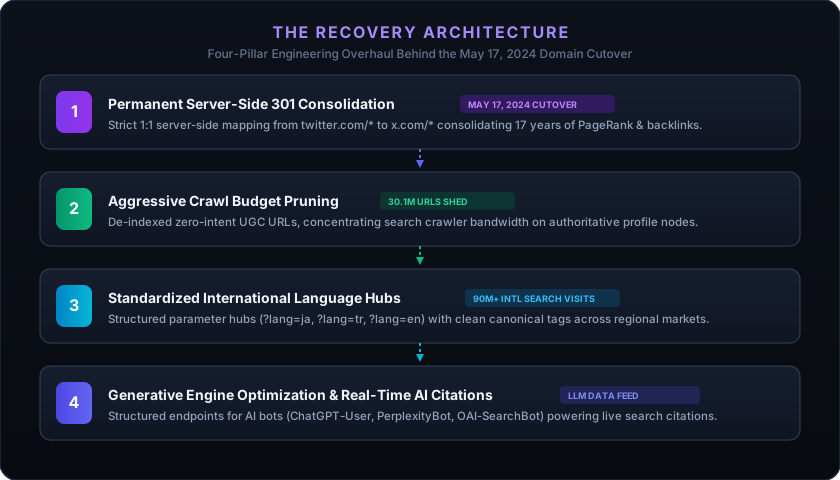
Resolving the search drop required an infrastructure rebuild, which culminated in the final domain cutover on May 17, 2024:
1. Server-Side 301 Consolidation (The May 17, 2024 Cutover)
Engineering removed the dual-domain setup. Every endpoint on twitter.com/* was mapped via server-side HTTP 301 redirects to its matching path on x.com/*.
This configuration allowed Googlebot to transfer accumulated backlink equity, historical authority, and entity connections directly to x.com. Within weeks, Google dropped legacy twitter.com URLs from its main index and restored ranking positions under x.com.
2. Crawl Budget Pruning: De-Indexing 30.1M Low-Value URLs
Instead of keeping every zero-engagement reply, bot interaction, and temporary post in the search index, the engineering team applied stricter crawl controls:
- The site removed roughly 30.1 million low-value, zero-click URLs from indexation.
- Crawl activity shifted toward high-authority profile hubs, verified brand accounts, and active public discussion threads.
3. Standardised International Language Hubs
To organise global search traffic, X standardised its URL parameter structure with canonical tags across major language markets. Ahrefs geographic data reflects this distribution:
- United States Hub: 83.0M monthly visits (22.6% of global organic traffic).
- Japan Hub (`?lang=ja`): 63.7M monthly visits (17.3% of traffic).
- Latin America and Europe Hubs: Direct parameter routing across Portuguese, Turkish, and Spanish hubs added over 90M monthly visits.
4. Generative Engine Optimisation (GEO) and Real-Time AI Search Citations
As search habits expanded toward conversational AI tools, X configured public endpoints to provide fast, structured data for large language models.
By maintaining accessible endpoints for verified AI user agents (ChatGPT-User, OAI-SearchBot, PerplexityBot), X became a primary source for live summaries and news citations across AI platforms.
The Recovery and New Baseline
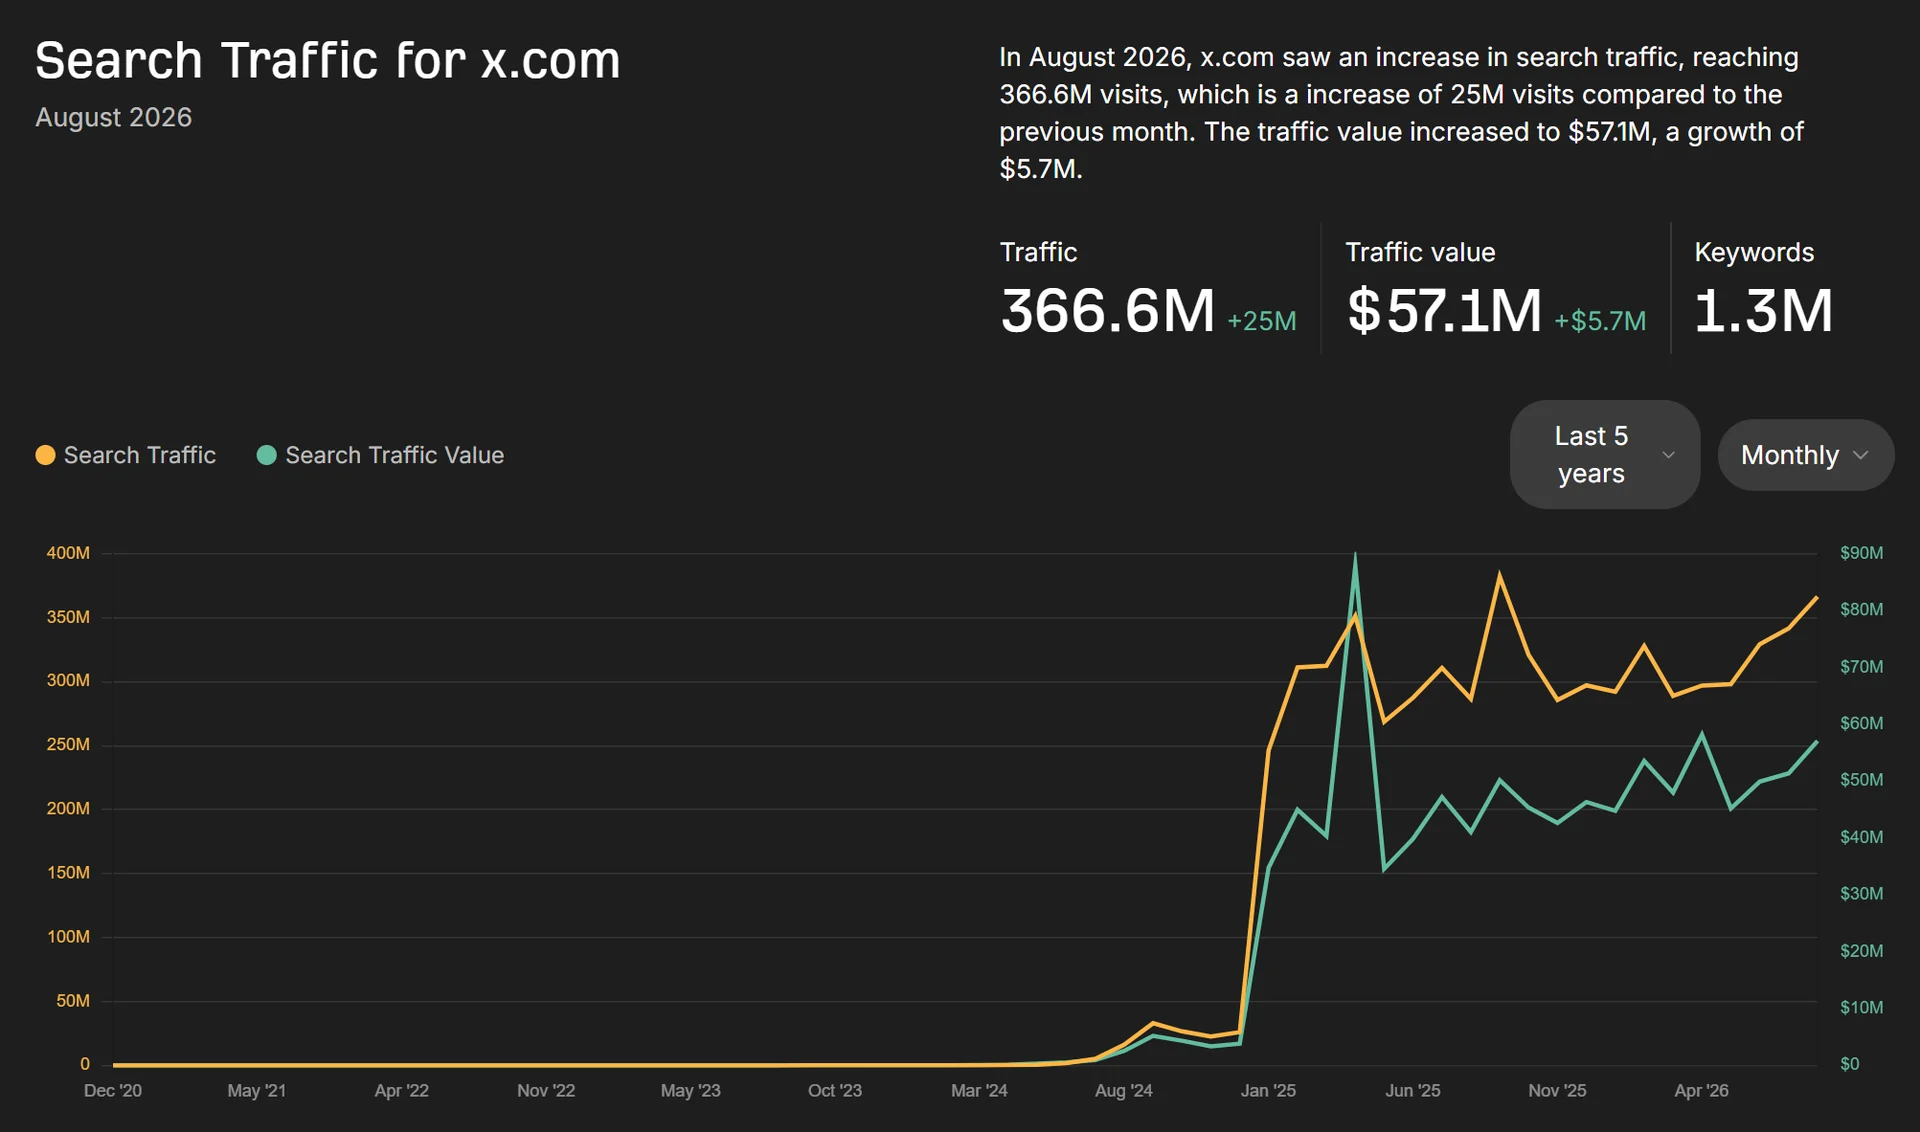
The technical updates resolved the crawl inefficiencies and consolidated domain signals under x.com:
Source: Search traffic telemetry and domain authority metrics from [Ahrefs Top Websites x.com profile](https://ahrefstop.com/websites/x.com).
1. Higher Traffic Concentration Across High-Intent Keywords
- Total Keywords: Reduced from 48.0M to high-intent clusters after pruning 30M unranked queries.
- Informational Search Traffic: Grew to 269.4M monthly visits.
- Navigational and Branded Traffic: Reached 71.6M monthly visits.
2. Visibility Across AI Search Engines
Clean crawling endpoints and distinct entity signals helped X gain prominent citation placement across AI search tools:
- AI Platform: Cited Pages: Growth Shift
- Google AI Overviews: 110,000 pages: +100,000 pages (+909%)
- ChatGPT (OpenAI Search): 61,100 pages: +42,300 pages (+225%)
- Perplexity AI: 42,300 pages: +57,400 pages (Active)
- Microsoft Copilot: 300+ pages: +201 pages
Technical Health and Lingering Opportunities
Crawl telemetry from x.com shows solid status code management following the domain consolidation:
- HTTP 200 OK (37.6%): Indexable profile and discussion pages.
- HTTP 3xx Redirects (57.7%): Legacy link mappings transferring link equity.
- HTTP 404 Errors (4.6%): Expected responses for deleted or pruned historical URLs.
Unclaimed Link Equity
Despite the successful cutover, over 21,580 broken backlink clusters remain unmapped across Wikipedia references, news embeds, and external tools. For any enterprise undergoing a major site migration, systematic link reclamation provides a reliable way to recover lost equity.
Key Takeaways for Enterprise Migrations
- Authentication Walls Stop Crawlers: Restricting public content behind login modals without dedicated crawler access will quickly reduce indexed pages and search visibility.
- Use Server-Side 301 Redirects: Temporary 302 codes and client-side JavaScript redirects prevent PageRank transfer. Permanent 301 redirects are required from day one of any migration.
- Pruning Low-Value URLs Protects Crawl Efficiency: Removing millions of thin, zero-click pages directs search engine crawlers toward authoritative, revenue-driving pages.
- Structured Entity Signals Matter for Modern Search: Search engines and AI models prioritise verified organisation data and consistent Knowledge Graph associations over raw keyword volume.
Need guidance navigating an enterprise website migration or brand consolidation?